Artificial intelligence can identify people, animals, vehicles, products, and other objects in digital images. But how does AI know what an object is and where it appears? Modern computer vision systems use trained models to analyze visual information and predict object locations, usually with bounding boxes and confidence scores. In this guide, you'll learn how AI object detection works, how popular models identify objects, how detection differs from image segmentation, and why these technologies matter for applications such as automatic background removal.
What Is AI Object Detection?
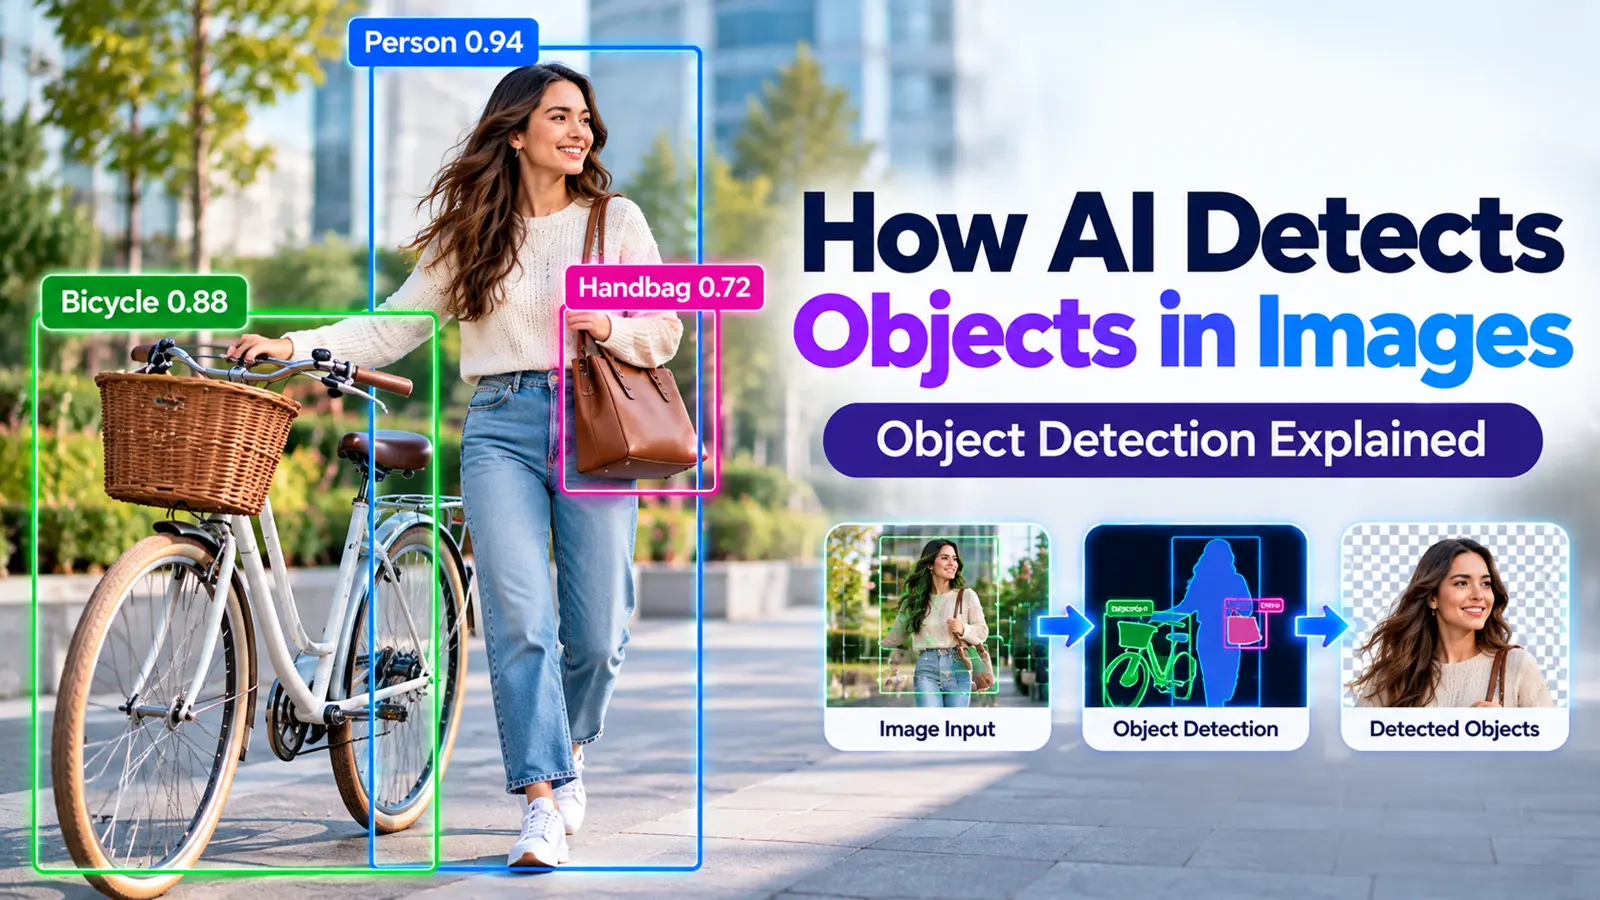
AI object detection is a computer vision task that identifies and locates objects in an image. A typical detection model predicts an object category, a bounding box describing its position, and a confidence score for each detected object.
For example, an image contains a woman holding a handbag beside a bicycle. AI may detect:
Person
Handbag
Bicycle
Each object can receive a bounding box and a predicted category. The model isn't identifying the person's real-world identity — it's recognizing the visual pattern of "a person" as a category.
How Does AI Detect Objects in Images?
Image input. The system receives a digital image.
Image preprocessing. The image may be resized or normalized for model inference.
Feature extraction. The model analyzes learned visual representations.
Object predictions. The model predicts object categories, locations, and scores.
Post-processing. Overlapping or low-scoring predictions may be filtered out.
Detection output. The system returns labeled object locations.
This is a simplified pipeline — some modern architectures combine or replace particular stages, so not every detector follows this exact sequence.
How Do Computers Understand Digital Images?
A digital image is made up of pixel values, and models process these values to learn visual representations. A few concepts come up repeatedly:
Pixels
Channels
Spatial patterns
Edges and textures
Shapes
Context
Learned features
AI models process images differently from the human visual system, even when their predictions appear similar to human recognition.
What Is Feature Extraction in Object Detection?
Feature extraction transforms raw image data into useful representations. Examples of the visual information involved:
Local edges
Textures
Shapes
Object parts
Spatial relationships
Larger scene context
Modern deep learning systems learn many of these representations automatically from training data, rather than relying on hand-designed rules for each one.
What Is a Bounding Box?
A bounding box is a rectangular region used to describe an object's approximate location. It can be represented by left/top/right/bottom coordinates, or by a center point plus width and height.
Important: bounding boxes locate objects approximately — they don't trace an object's exact silhouette. A box around a person includes some background pixels along with the person.
What Is a Confidence Score in Object Detection?
A confidence score expresses a model's degree of support for a prediction, according to its own scoring method. For example:
Person — 0.94
Bicycle — 0.88
Handbag — 0.72
These are illustrative values, not measured outputs from a real system.
An important nuance: a 0.94 score doesn't automatically mean a calibrated 94% probability that the prediction is correct. Different models define and calibrate confidence scores differently, so scores aren't always directly comparable across systems.
How Does AI Detect Multiple Objects?
A detector can produce multiple predictions from a single image, but a few things make this harder than it might sound:
Overlapping objects
Multiple objects of the same class
Small objects
Partially hidden objects
Duplicate predictions for the same object
This is where post-processing and object-instance separation come in, including the technique covered next.
What Is Non-Maximum Suppression (NMS)?
Non-Maximum Suppression is a common technique used to reduce duplicate, overlapping detections of the same object. A simplified version of how it works:
Compare overlapping predicted boxes.
Prioritize the highest-scoring prediction.
Suppress sufficiently overlapping alternatives under the chosen method.
Retain the remaining predictions.
Not every modern detector uses traditional NMS — some architectures use alternative prediction and matching strategies instead.
How Are AI Object Detection Models Trained?
A typical supervised training workflow includes:
Collect images
Annotate objects
Prepare training data
Train the model
Validate predictions
Evaluate performance
Improve the data or model
Deploy for inference
The model learns from examples rather than requiring a hand-written rule for every possible object appearance.
What Are Object Detection Annotations?
Training datasets commonly include an image, an object class, bounding box coordinates, and sometimes additional attributes or segmentation masks. For example:
Image: street_photo.jpg — Object 1: Class: Person, Bounding box: [40, 30, 160, 310] — Object 2: Class: Bicycle, Bounding box: [180, 140, 340, 290]
These coordinates are illustrative, not measured values.
Why Does Training Data Matter?
Model performance depends partly on:
Dataset diversity
Image quality
Annotation consistency
Object categories covered
Lighting conditions
Background variety
Camera angles
Small and large object examples
Real-world deployment conditions
A model trained mostly on one kind of image can struggle on genuinely different ones — this is often called dataset bias or domain shift, and it affects virtually every trained model to some degree, not just a specific product or vendor.
What Is Deep Learning Object Detection?
Deep learning object detectors use neural networks to learn visual representations and predict object locations and classes. Common architectural concepts include:
Backbones
Feature pyramids
Detection heads
Classification predictions
Box regression
Not every detector uses the exact same arrangement of these components.
What Are the Main Types of Object Detectors?
Two-stage detectors. Commonly generate candidate regions and then refine and classify them.
One-stage detectors. Predict object locations and categories through a more direct detection pipeline.
Transformer-based detectors. Often use object queries and set-prediction approaches.
Not every model fits perfectly into just two categories — this is a useful simplification rather than a strict taxonomy.
One-Stage vs Two-Stage Object Detection
One-stage doesn't automatically mean less accurate, and two-stage doesn't automatically mean better — the right choice depends on the specific task, hardware, and accuracy requirements.
What Is YOLO Object Detection?
YOLO stands for "You Only Look Once." The YOLO family is known for approaches designed to perform object detection efficiently, with a focus on:
Object localization
Class prediction
Real-time applications
Model-size tradeoffs
Different YOLO versions aren't one identical architecture — the family has evolved across multiple releases with different design choices.
How Does Faster R-CNN Work?
Faster R-CNN is a two-stage object detection architecture. At a high level, the flow looks like:
Image
↓
Feature Extraction
↓
Region Proposals
↓
Object Classification and Box Refinement
The region-proposal step is typically handled by what's called a Region Proposal Network (RPN), which suggests candidate areas that the rest of the model then classifies and refines.
What Is SSD Object Detection?
SSD stands for Single Shot MultiBox Detector. It predicts object categories and bounding boxes from feature representations at different scales, and is a useful historical and architectural example of one-stage detection.
What Is DETR?
DETR stands for DEtection TRansformer. It introduced a transformer-based set-prediction approach to object detection, built around a few key ideas:
Object queries
Attention-based representations
Bipartite matching during training
An end-to-end prediction formulation
DETR has multiple successors and variants, so it's best thought of as the starting point of a family rather than a single fixed model.
YOLO vs Faster R-CNN vs DETR
This guide doesn't report specific speed, FPS, mAP, or accuracy benchmarks for these models — meaningful comparisons require the same dataset, evaluation setup, hardware, and model configuration, and numbers taken out of that context can be misleading.
Object Detection vs Image Classification
A quick example: classification might say "bicycle present," while detection says "bicycle, at this particular location in the image."
Object Detection vs Image Recognition
Image recognition is a broad term covering tasks that identify visual content in general. Object detection is a more specific task that involves both identifying what's present and locating where it is. Although the terms are sometimes used interchangeably in casual conversation, they are not exact synonyms.
Object Detection vs Image Segmentation
For the full explanation of how segmentation works, including semantic, instance, and panoptic segmentation, see AI Image Segmentation Explained.
Object Detection vs Instance Segmentation
Detection identifies approximate object locations with boxes. Instance segmentation identifies separate object regions at the pixel level.
For example, if two people overlap in a photo, detection can produce two bounding boxes, while instance segmentation can predict a separate pixel-level mask for each person. The quality of these masks depends on the model and image conditions.
Object Detection vs Image Localization
Image localization often refers specifically to predicting the location of an object, typically through a box. Object detection usually extends this further, to identifying and locating multiple objects and categories at once. Terminology here can vary somewhat across different educational materials and papers.
How Does AI Recognize People in Images?
A person detector learns visual patterns associated with people, and may identify full-body people, partially visible people, people at different scales, and people in different poses.
An important distinction: person detection does not inherently identify who a specific person is. That's a separate task — facial recognition — and shouldn't be confused with general object detection.
How Does AI Detect Small Objects?
Small objects are genuinely harder to detect, for a few concrete reasons:
Few pixels to work with
Weak visual features
Scale differences relative to other objects
Image resizing that shrinks detail further
Crowded scenes
Approaches that can help include multi-scale features, higher-resolution inputs, task-specific training, and detection architectures suited to the task — but no method guarantees reliable small-object detection in every case.
How Does AI Detect Overlapping Objects?
This involves handling occlusion, multiple candidate boxes, object-level predictions, duplicate suppression, and contextual information. Overlapping people or products can genuinely be challenging, since the model has to decide where one object ends and another begins.
How Does AI Detect Objects Against Complex Backgrounds?
AI can rely on more than simple color contrast — it may learn shape patterns, texture, context, object parts, and spatial relationships. Even so, complex backgrounds, camouflage-like patterns, and visually similar objects can still cause errors.
How Object Detection Helps AI Background Removal
At a conceptual level, object detection can play a role in identifying and locating a subject before more detailed processing takes over:
Original Photo
↓
Identify Subject / Object
↓
Locate Relevant Region
↓
Generate or Refine Subject Mask
↓
Estimate Fine Boundaries / Alpha
↓
Remove Background
↓
Transparent PNG
This is one possible conceptual pipeline, not a claim about ByByBG's actual model architecture. Some background-removal systems directly predict foreground masks without a separate bounding-box detection stage at all.
Why Object Detection Alone Cannot Remove Backgrounds Precisely
A bounding box contains both object pixels and background pixels inside the rectangle — it's a rough region, not a precise outline. For a natural transparent cutout, the system needs much finer subject boundaries than a box can provide.
Additional techniques that help close this gap include:
Segmentation
Alpha matting
Boundary refinement
Image compositing
Object Detection vs Background Removal
For the full explanation of how background removal actually works, see How AI Background Removal Works.
Why AI Sometimes Fails to Detect Objects
Common reasons include:
Motion blur
Low resolution
Unusual viewpoints
Partial occlusion
Poor lighting
Crowded scenes
Similar-looking objects
Domain shift from the training data
Training-data limitations
Very small objects
Detection errors can result from several factors, including image quality, scene complexity, training data, and model architecture.
False Positives vs False Negatives
False positive. AI reports an object that should not have been detected — for example, labeling a shadow as a person.
False negative. AI misses an object that should have been detected — for example, not detecting a person who is actually in the image.
These two error types trade off against each other, which is often described as the precision-recall tradeoff, covered in more detail below.
How Is Object Detection Accuracy Measured?
A few metrics come up repeatedly in this field:
Precision
Recall
Intersection over Union (IoU)
Average Precision (AP)
Mean Average Precision (mAP)
A detector has to predict both the correct category and a sufficiently accurate location to count as correct under most evaluation setups.
What Is Intersection over Union (IoU)?
IoU compares the overlap between a predicted bounding box and its reference box — the overlapping area divided by the combined (union) area of both boxes. Higher overlap generally means closer localization, but IoU alone doesn't measure a detector's entire quality, since it says nothing about the category prediction or confidence calibration.
What Is Precision and Recall?
Precision. Among the predictions the model made, how many were actually correct?
Recall. Among the objects that were actually present, how many did the model successfully detect?
A simple example: if a model makes 10 predictions and 8 are correct, precision is 80%. If there were actually 12 objects in the image and the model found 8 of them, recall is about 67%. Both numbers depend on clearly defined matching criteria.
What Is mAP in Object Detection?
mAP stands for mean Average Precision. Average Precision (AP) summarizes detection performance across confidence thresholds under a given evaluation protocol, and mAP averages AP values across classes and, depending on the benchmark, across IoU thresholds too.
Important: mAP@0.5 and COCO-style mAP@0.5:0.95 are not directly interchangeable. Reported mAP values shouldn't be compared across sources without checking that they used the same evaluation protocol.
Can AI Detect Objects in Real Time?
Yes, depending on model size, hardware, input resolution, the number of objects, inference optimization, and the required latency. Examples include live camera applications, robotics, video analytics, and industrial inspection.
Real-time performance isn't guaranteed on every device — a model that runs smoothly on dedicated hardware may run far more slowly on a typical phone or laptop.
Object Detection on Mobile Devices
Running detection on a phone involves its own set of tradeoffs: on-device inference, smaller model architectures, battery and memory limits, latency, privacy considerations, and whether offline processing is even possible for the task.
Not all AI detection tools process images locally on the device — many rely on server-side processing instead.
Real-World Applications of AI Object Detection
Object detection shows up across a wide range of fields:
Photo editing
E-commerce
Autonomous driving
Robotics
Manufacturing
Agriculture
Medical imaging
Retail inventory
Wildlife monitoring
Accessibility tools
Object Detection in Photo Editing
Identifying a person in a photo
Selecting objects for editing
Preparing object-specific edits
Assisting background removal
Organizing image assets
This is the area most directly connected to tools like ByByBG, where locating a subject is a useful early step before more detailed background removal.
Object Detection in E-commerce
Product localization
Catalog analysis
Visual search
Inventory imaging
Object selection for image editing
For sellers specifically, see How to Remove Background from Product Photos.
Object Detection in Autonomous Driving
Vehicles
Pedestrians
Cyclists
Road signs
Safety-critical perception in self-driving systems requires additional sensors, validation, and redundancy — object detection alone is not sufficient for autonomous driving.
Object Detection in Agriculture
Fruit counting
Crop monitoring
Weed detection
Pest detection
Agricultural robotics
Detection performance here depends heavily on crop conditions and properly validated training data for the specific crops and environments involved.
Object Detection in Manufacturing
Identifying parts
Counting products
Detecting missing components
Supporting quality inspection
Locating an object and identifying defects are different tasks. Defect detection often requires specialized training and evaluation.
Object Detection in Medical Imaging
Localizing suspicious image regions
Assisting radiology workflows
Finding anatomical structures
Medical uses require clinical validation and appropriate expert review — detection output should support a diagnosis made by a qualified professional, not stand in as one on its own.
What Are the Limitations of AI Object Detection?
Dataset dependence
Distribution shifts between training and real-world data
False detections
Missed objects
Occlusion
Small-object challenges
Computational cost
Domain-specific performance
Confidence calibration
Annotation quality
There are ethical considerations here too — object and person detection can be misused for inappropriate surveillance or privacy-invasive purposes, which is worth keeping in mind for any deployment.
What Is the Future of AI Object Detection?
A few directions current research points toward, framed as areas of active work rather than guaranteed outcomes:
Open-vocabulary object detection
Text-guided object localization
More efficient on-device models
Better small-object detection
Stronger video understanding
Closer integration with segmentation
More capable multimodal visual systems
Try AI Background Removal with ByByBG
Object detection helps explain how AI systems identify and locate visual subjects. For image editing, more detailed foreground selection and transparency processing can turn that understanding into a clean cutout. Try ByByBG to remove the background from your photo and download a transparent PNG.
Remove Image Background with AI →
Frequently Asked Questions
How does AI detect objects in images?
A trained model analyzes an image's visual features and predicts object categories, their approximate locations as bounding boxes, and a confidence score for each detection.
What is AI object detection?
AI object detection is a computer vision task that identifies and locates objects within an image, typically outputting a category, a bounding box, and a confidence score for each one.
How does AI recognize objects in pictures?
The model learns visual patterns — edges, textures, shapes, and context — from training data, then uses those learned patterns to recognize similar objects in new images.
What is a bounding box?
A bounding box is a rectangle that marks an object's approximate location in an image. It locates the object but doesn't trace its exact outline.
What is a confidence score?
A confidence score reflects how strongly a model supports a given prediction, according to its own scoring method — it isn't always a precisely calibrated probability.
How are object detection models trained?
Models are trained on datasets of annotated images, where each object is labeled with its category and bounding box, so the model can learn to predict similar outputs on new images.
What is YOLO object detection?
YOLO ("You Only Look Once") is a family of one-stage object detection models designed for efficient, fast object localization and classification.
What is the difference between YOLO and Faster R-CNN?
YOLO is generally a one-stage, efficiency-focused approach, while Faster R-CNN is a two-stage architecture that first proposes candidate regions and then classifies and refines them.
What is object detection vs image classification?
Classification identifies what's in an image overall, while object detection identifies specific objects and their approximate locations within the image.
What is object detection vs image segmentation?
Detection locates objects with bounding boxes, while segmentation identifies the exact pixels belonging to each object — segmentation produces a far more detailed outline.
Can object detection remove image backgrounds?
Object detection alone isn't precise enough for a clean transparent cutout, since a bounding box includes background pixels. It can help locate a subject, but segmentation and alpha matting are what produce natural-looking edges.
Why does AI fail to detect some objects?
Common causes include motion blur, low resolution, poor lighting, occlusion, crowded scenes, unusual viewpoints, and objects that differ significantly from the model's training data.
How is object detection accuracy measured?
Common metrics include precision, recall, Intersection over Union (IoU), Average Precision (AP), and mean Average Precision (mAP).
Can AI detect multiple objects in one image?
Yes. A detector can predict multiple objects in a single image, though overlapping or very similar objects can make this more challenging.
Can AI detect objects in real time?
Yes, depending on the model, hardware, and required accuracy — some models are specifically designed for real-time use, though performance varies by device.
Conclusion
Object detection is the computer vision task that teaches AI systems to answer "what objects are here, and roughly where?" using bounding boxes and confidence scores. It's a useful building block for scene understanding and photo editing, but it stops short of the pixel-level precision that a clean transparent cutout needs — that next level of detail is where image segmentation and alpha matting take over.
Ready to see it in action? Remove Image Background with AI →